Site Reliability Engineer Jobs

1,083 jobs found — updated daily

About The Position

SpaceX is seeking an experienced engineer with deep working knowledge of virtualization, infrastructure, and compute. As a member of the Information Technology Infrastructure team, this employee will provide expertise in virtualization and compute, maintenance, scaling, and optimization in support of critical business functions. The ideal candidate is flexible, self-starting, self-motivated, and inventive, and can thrive in a fast-paced, challenging environment.

Requirements

  • Bachelor’s degree in Computer Science or a STEM discipline and at least 1 year of systems engineering experience, or at least 3 years of systems engineering experience in lieu of a degree.
  • Experience deploying and supporting Linux servers in physical and virtualized environments, such as VMware via automation.
  • Experience with the Linux shell and configuring and extending Linux instances, such as kernel modules, cgroups, PKI, iptables, and interfaces.
  • Must be willing to work extended hours and weekends as needed.
  • Must meet SpaceX's stated ITAR eligibility requirements: be a U.S. citizen or national, a U.S. lawful permanent resident, a refugee under 8 U.S.C. § 1157, an asylee under 8 U.S.C. § 1158, or be eligible to obtain the required U.S. Department of State authorizations.

Nice To Haves

  • Experience creating repeatable, reliable, scalable systems architectures with high availability, fault tolerance, performance tuning, monitoring, and statistics or metrics collection.
  • Experience operating production virtualization platforms such as VMware vSphere/vCenter (clustering, HA, DRS, vMotion, and datastore design), Hyper-V, or KVM.
  • Experience architecting and operating enterprise storage, including NFS, SMB/CIFS, iSCSI, Fibre Channel, NVMe-oF, NetApp, Pure Storage, and object storage.
  • Expertise generating server and host design specifications—including CPU, memory, NIC, HBA, and local versus shared storage—to meet performance, availability, and density requirements.
  • Experience with array- and hypervisor-based snapshots, replication, and backup integration for virtual machine and storage recovery.
  • Ability to diagnose compute and storage performance issues, including IOPS, latency, queue depth, CPU ready/co-stop, datastore contention, and fabric/pathing.
  • Experience implementing configuration management, provisioning, and workflow automation through infrastructure as code and CI/CD, such as Ansible, AWX/Tower, Puppet, cloud-init, and Jenkins.
  • Experience with programming and scripting languages such as Python, PowerShell, or Golang to automate tasks and integrate with external systems through RESTful APIs.
  • Experience implementing proactive alerting and monitoring workflows and dashboards for Linux systems and virtualization platforms using Prometheus, Grafana, InfluxDB, or similar technologies.
  • Experience supporting and scaling containerized applications in Linux environments.
  • Experience using automation frameworks such as Ansible or Terraform to manage infrastructure provisioning and post-provisioning lifecycles, including Kubernetes installations.

Responsibilities

  • Design, install, operate, scale, and optimize enterprise compute, virtualization, and storage platforms, including hypervisor clusters, purpose-built servers, and high-performance NAS, SAN, and object storage.
  • Work with SpaceX engineers to gather requirements and design, deploy, and support resilient, high-performance systems for engineering, production, and mission workloads.
  • Perform capacity planning and performance engineering, and implement high availability, backup, replication, and disaster recovery for virtual machines, datastores, and storage arrays.
  • Install, configure, patch, and decommission servers, hypervisor hosts, and storage systems, and contribute to hardware and platform standards.
  • Automate provisioning, patching, and day-to-day operations with scripting, templates, and infrastructure as code to reduce toil.
  • Document standards and best practices, and partner with network, facilities, security, and application teams on connectivity, power and cooling, access, and workload placement.

Career Resources

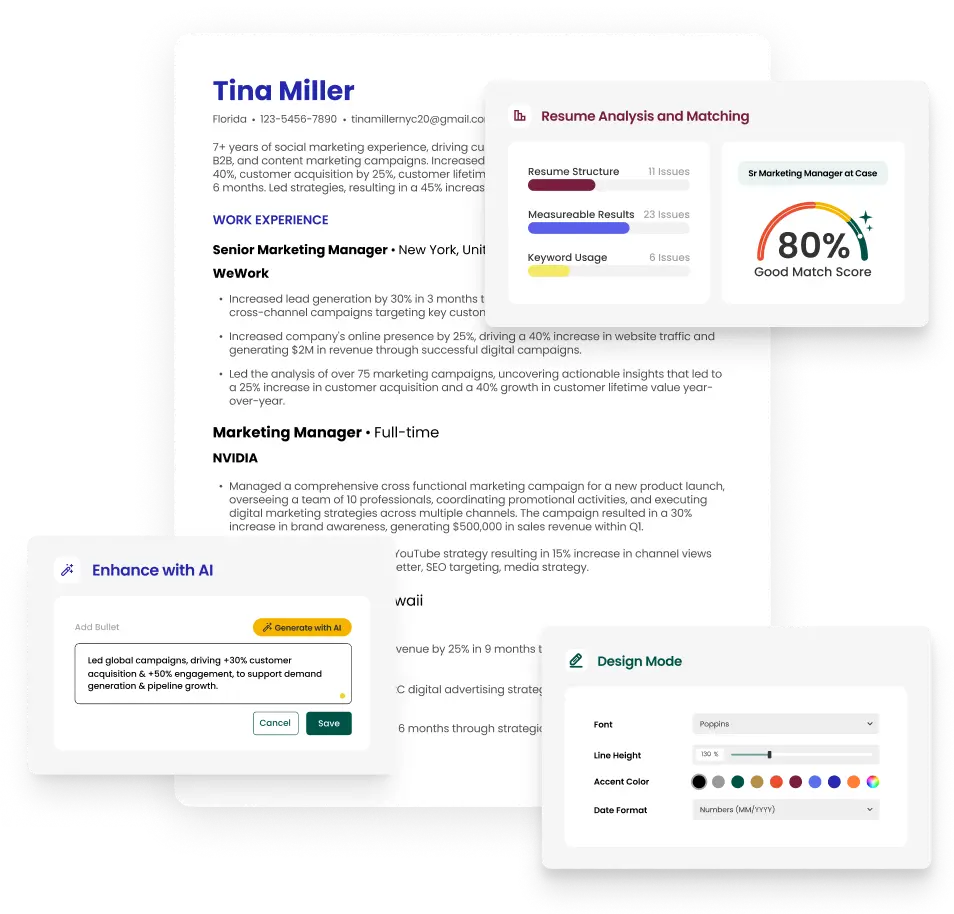
Build a Resume for Site Reliability Engineer
The resume builder that gets results.

  • Get clear feedback so you look as qualified as you are
  • Align your resume with the job to get further in the process, faster
  • Take the guesswork out of resume writing

Explore Related Job Searches

© 2026 Teal Labs, Inc
Privacy PolicyTerms of Service