Engineer Jobs

10,000 jobs found — updated daily

Software Engineer II

Bank of America•Jersey City, NJ
•$88,800 - $144,800•Onsite

About The Position

At Bank of America, the Software Engineer II develops and delivers complex requirements to accomplish business goals. The role ensures software meets functional, non-functional, and compliance requirements; codes and unit tests solutions; and ensures successful integration into the overall application or system through clear, robust, well-tested interfaces. The position calls for awareness of industry development and testing practices. The description also outlines responsibilities for a Senior Site Reliability Engineer (SRE) for the AI HPC Platform. This role supports the reliability, scalability, performance, security, and operational excellence of a large-scale AI and High-Performance Computing (HPC) environment. It combines software engineering, systems administration, automation, and operations to support AI/ML model development, training, inference, and production workloads on GPU infrastructure. The engineer advances platform stability through observability, automation, incident management, capacity planning, and continuous improvement. The position is based at 101 Hudson St in Jersey City, New Jersey. It is a first-shift role with 40 hours per week. The listed annualized salary range is $88,800 to $144,800; offers are determined based on experience, education, and skill set. The role is eligible for an annual discretionary incentive plan and benefits, including paid time off.

Requirements

  • At least 5 years of experience in Site Reliability Engineering, Infrastructure Engineering, Systems Engineering, or Platform Operations.
  • Strong expertise administering Linux and Unix operating systems in large-scale enterprise environments.
  • Hands-on experience with HPC platforms.
  • Strong experience administering and troubleshooting SLURM workload managers.
  • Experience supporting Red Hat OpenShift and Kubernetes-based container platforms.
  • Deep understanding of monitoring and observability platforms, including Grafana.
  • Experience managing PostgreSQL databases in production environments.
  • Experience supporting Redis clusters and caching technologies.
  • Strong knowledge of networking, storage, security, and enterprise infrastructure concepts.
  • Experience with scripting and automation using Python, Bash, or similar languages.
  • Experience leading production incident response and root-cause analysis.
  • Knowledge of high-availability architectures, disaster recovery, and resilience engineering practices.

Nice To Haves

  • Bachelor's degree in Computer Science, Engineering, Information Systems, or a related field, or equivalent experience.
  • Experience supporting AI/ML, LLM, GPU, or GenAI platforms.
  • Experience managing NVIDIA GPU infrastructure, GPU operators, and AI workloads.
  • Familiarity with vLLM Inference Server, JupyterHub, or AI development platforms.
  • Experience with Infrastructure-as-Code tools such as Ansible or Terraform.
  • Experience with CI/CD pipelines and DevOps methodologies.
  • Knowledge of Prometheus, Elasticsearch, Loki, or other observability technologies.
  • Understanding of enterprise vulnerability management and regulatory compliance processes.
  • Experience working in highly regulated financial services or large enterprise environments.
  • Certifications such as Certified Kubernetes Administrator (CKA), Red Hat OpenShift Administration Certification, Google SRE Certification, Red Hat Certified Engineer (RHCE), or AWS/Azure Cloud Certifications.

Responsibilities

  • Code solutions and unit test them to deliver requirements or stories according to acceptance and compliance criteria.
  • Use multiple architectural components across data, application, and business domains in designing and developing client requirements.
  • Perform Continuous Integration and Continuous Development (CI/CD) activities.
  • Contribute to story refinement and requirements definition.
  • Estimate the work required to deliver stories or requirements through the delivery lifecycle.
  • Contribute to integration, regression, and performance test suites; analyze reports, identify issues or errors, and triage their underlying causes.
  • Perform spikes or proofs of concept as needed to mitigate risk or implement new ideas.
  • Ensure availability, reliability, scalability, and performance of AI HPC infrastructure supporting AI/ML training and inference workloads.
  • Administer and optimize Linux/Unix-based HPC environments for stable, secure, and efficient operations.
  • Manage and optimize SLURM workload scheduling, GPU resource allocation, queue management, and cluster utilization.
  • Design, implement, and maintain observability and monitoring solutions using Grafana and related technologies.
  • Support and administer OpenShift container platforms for reliable deployment and operation of AI services.
  • Manage PostgreSQL and Redis environments, including performance tuning, backup and recovery, and high-availability configurations.
  • Lead production incident response, root-cause analysis, and problem management to improve platform resiliency.
  • Develop automation solutions, operational tooling, and Infrastructure-as-Code capabilities to improve reliability and operational efficiency.
  • Perform capacity planning and performance management for GPU, compute, storage, and networking resources.

Benefits

  • Benefits eligibility
  • Paid time off
  • Annual discretionary incentive plan

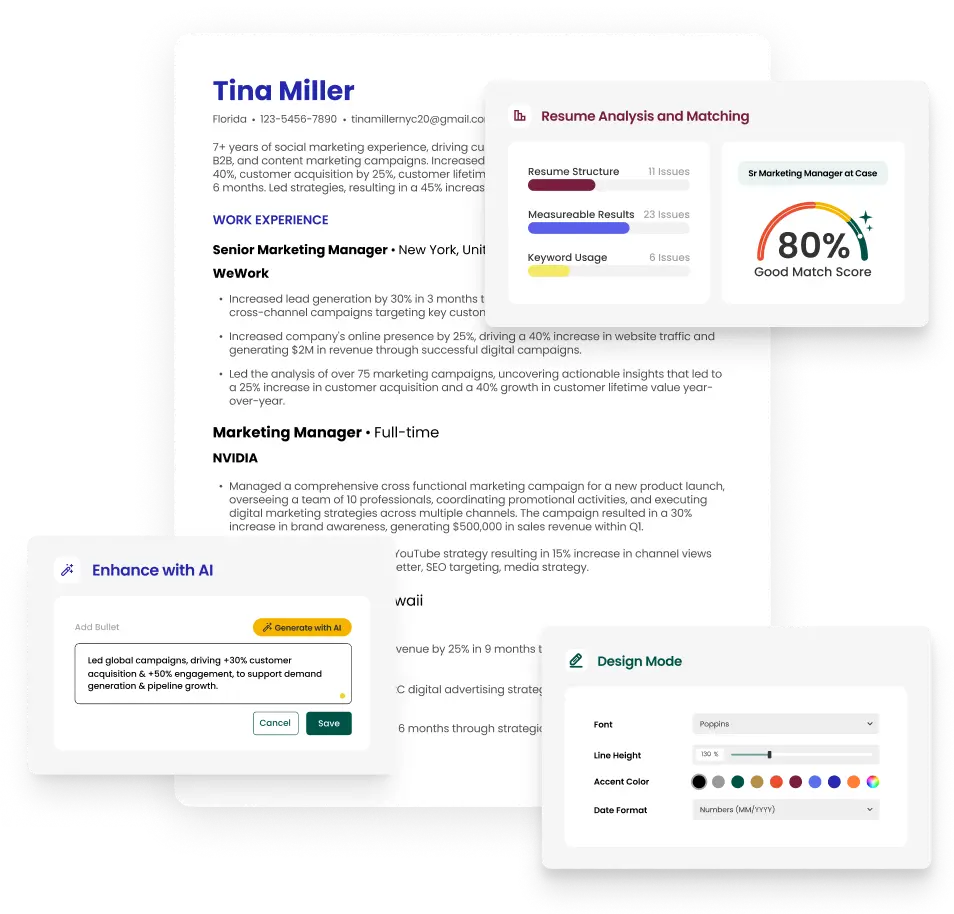
Build a Resume for Engineer

The resume builder that gets results.

  • Get clear feedback so you look as qualified as you are
  • Align your resume with the job to get further in the process, faster
  • Take the guesswork out of resume writing

Explore Related Job Searches

© 2026 Teal Labs, Inc
Privacy PolicyTerms of Service