Reliability Engineer Jobs

2,415 jobs found — updated daily

Site Reliability Engineer (US - Pacific time)
PostHog•San Francisco, CA
•Remote

About The Position

PostHog is hiring a Site Reliability Engineer based in the US Pacific time zone to help make its fast-growing, stateful production platform predictable and well automated. This is not a typical “keep the lights on” SRE role: the focus is on provisioning, scaling, rebalancing, and recovering infrastructure while reducing operational stress and building systems that scale without increasing human effort. The role works on large-scale systems handling petabytes of data, thousands of cores, and constant ingestion across a multi-region, multi-account AWS platform with many services on Kubernetes. The engineer will have ownership of production systems and opportunities to design automation and platform tooling, alongside participating in on-call and incident response. The team emphasizes reducing recurring operational work, improving reliability, and optimizing cloud spend.

Requirements

  • Deep hands-on experience with Kubernetes in production; EKS experience is preferred. Experience debugging node pressure, networking issues, and deployment failures at scale is required.
  • Strong experience operating production infrastructure on AWS, including organizational boundaries, IAM, and networking across multiple accounts.
  • Experience automating infrastructure at scale using Terraform or Terragrunt, including module design and state management.
  • Solid understanding of Linux systems, including disk, memory, networking, and failure modes.
  • Experience supporting stateful systems such as databases, queues, or storage systems.
  • Ability to debug and reason about production performance and reliability issues.
  • Comfort owning systems end to end, including on-call responsibilities.
  • Enjoyment of owning complex infrastructure and learning how its components fit together.
  • Proactive ownership of projects, with the judgment to seek help when needed.
  • Collaborative, resilient problem-solving and a kind, considerate, professional, low-ego, flexible, and respectful approach.

Nice To Haves

  • Experience with GitOps workflows such as ArgoCD and CI/CD pipelines such as GitHub Actions.
  • Experience building AI agent-enabled base-level infrastructure services for fast-moving teams.
  • Familiarity with multi-region infrastructure and its consistency and availability tradeoffs.

Responsibilities

  • Operate EKS clusters across several environments, including Karpenter autoscaling, Cilium networking, and ArgoCD-driven GitOps deployments.
  • Manage and evolve a multi-account AWS organization, including provisioning, networking, access control, and cross-account connectivity.
  • Maintain the Terraform/Terragrunt infrastructure-as-code platform, including modules, plan-on-PR/apply-on-merge pipelines, and safe patterns for shared infrastructure.
  • Improve operational tooling for deployments, schema changes, backups, restores, and incident response.
  • Identify recurring operational pain points and eliminate them through code and self-healing automation.
  • Optimize cloud spend.
  • Participate in on-call and incident response, with a focus on making incidents less frequent over time.
  • Own production systems end to end and build platform capabilities that support system scaling.

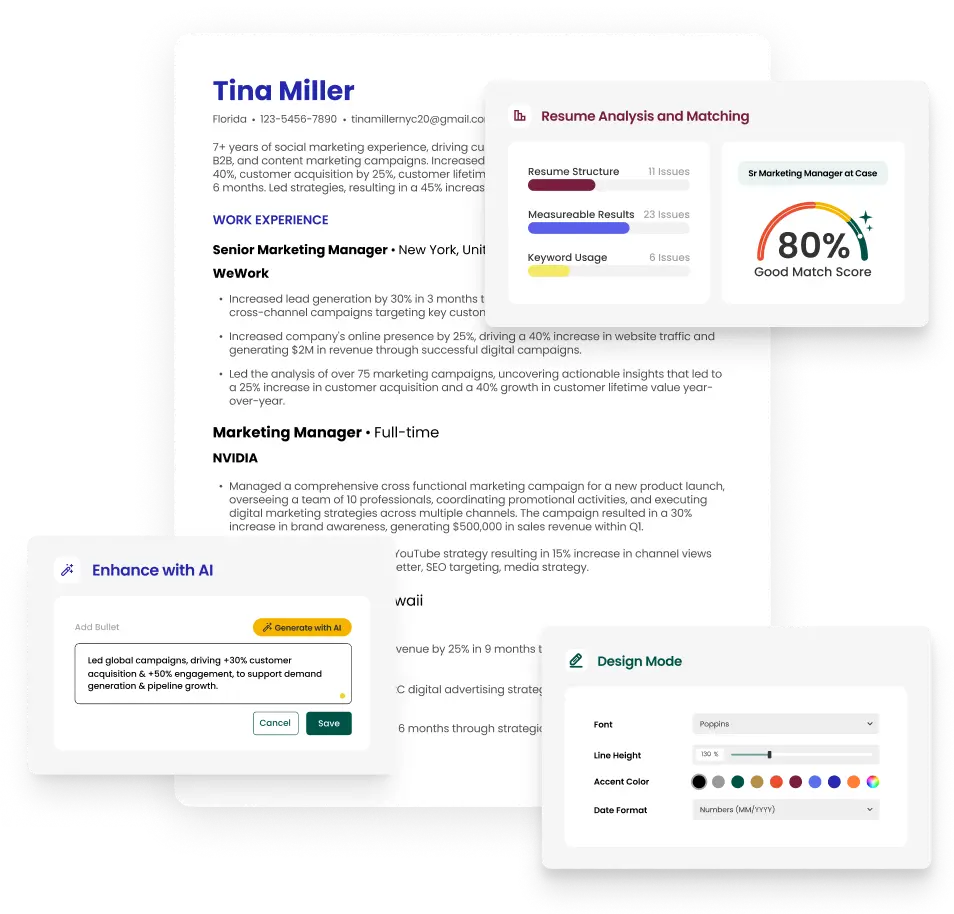
Build a Resume for Reliability Engineer

The resume builder that gets results.

  • Get clear feedback so you look as qualified as you are
  • Align your resume with the job to get further in the process, faster
  • Take the guesswork out of resume writing

Explore Related Job Searches

© 2026 Teal Labs, Inc
Privacy PolicyTerms of Service